NVIDIA Vera Rubin debuts at the top of MLPerf Training v6.1 as NVIDIA sweeps every benchmark
In MLPerf Training v6.1 results published by MLCommons on November 16, NVIDIA led all seven benchmarks, and its Vera Rubin NVL72 system delivered up to 2x the per-GPU performance of the GB300 NVL72.
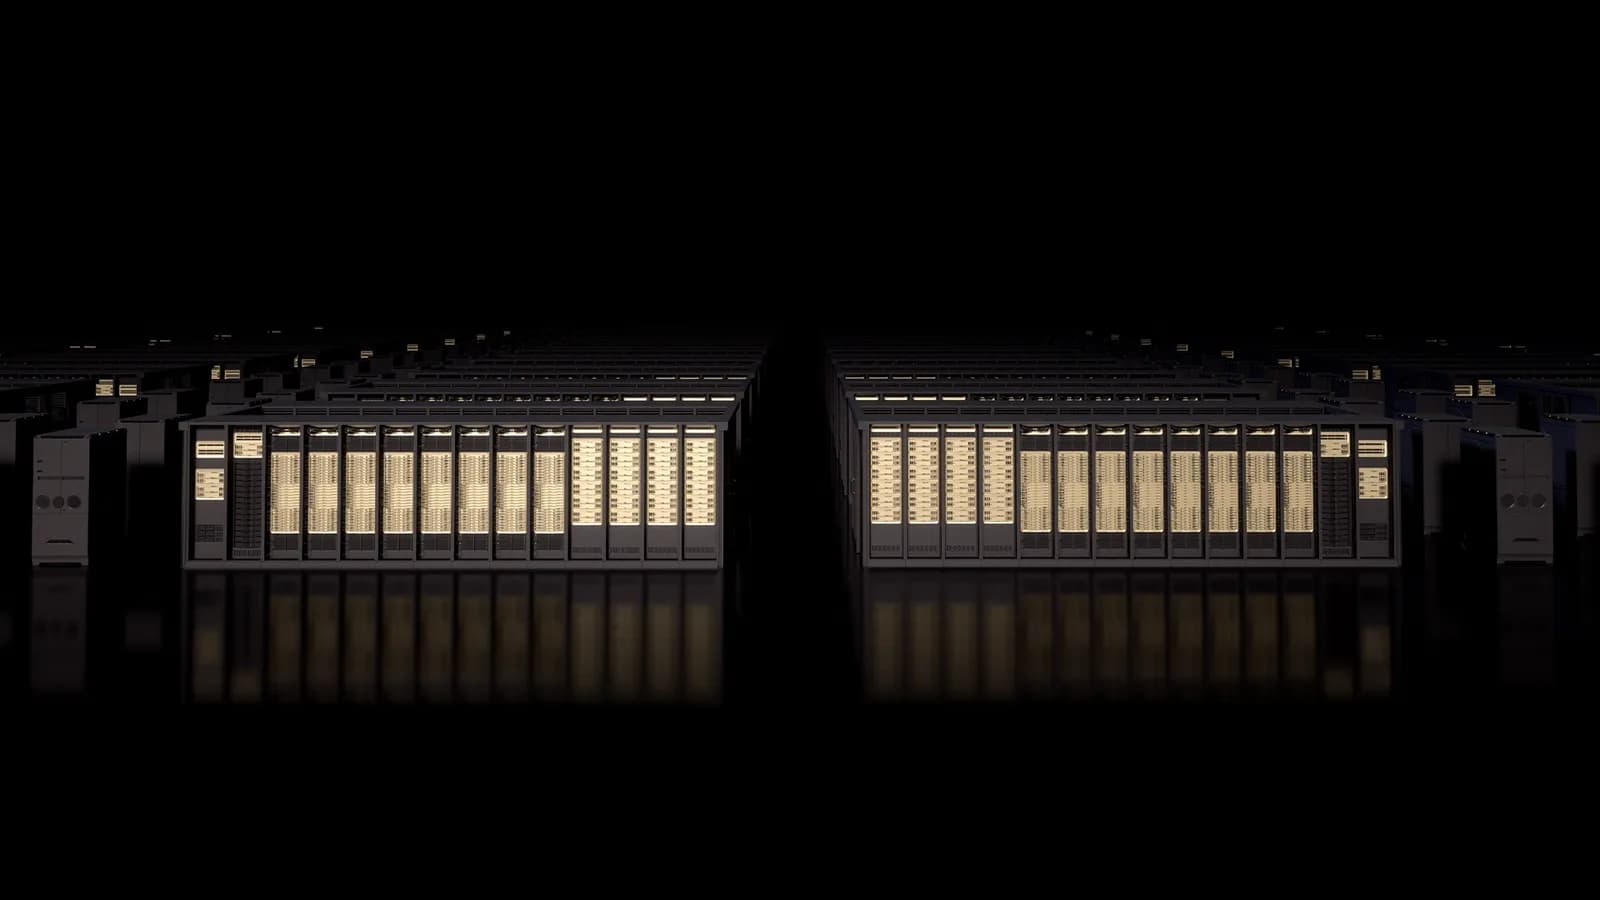
MLCommons published results for MLPerf Training v6.1, the industry benchmark for how fast systems train AI models to a target accuracy, on November 16. NVIDIA's next-generation Vera Rubin platform made its debut, and NVIDIA swept every benchmark in the round; the company said its platform was the only one with results on every test, spanning large language models, image generation, recommender systems and reinforcement-learning post-training.
Headline results
According to NVIDIA, Vera Rubin NVL72 delivered up to 2x more performance per GPU than the highly optimized GB300 NVL72. On the DeepSeek-V3 benchmark it scaled from 256 to 1,024 GPUs with about 97% efficiency, cutting training time from 16 minutes to about four. NVIDIA also ran the benchmark on 10,240 GPUs with GB300 systems, the largest scale in the round, and Microsoft Azure matched that scale with GB200 systems.
CoreWeave said it became the first cloud provider to deliver multi-rack Vera Rubin results, training DeepSeek-V3 in 17.65 minutes on a 256-GPU system.
Agentic inference and partners
In its first MLPerf Endpoints submission, NVIDIA said Vera Rubin NVL72 delivered more than 10x the throughput per watt of GB300 NVL72 on the Kimi K3 agentic workload, though that result is provisional and pending MLCommons verification. Twenty organizations submitted MLPerf Training results on NVIDIA's platform, including ASUS, Azure, Cisco, CoreWeave, Dell Technologies, Google Cloud, HPE, Lambda, Nebius, Oracle and Supermicro.
NVIDIA argued that faster training lets more capable agents reach users sooner and helps drug-discovery and fraud-detection models keep pace with new data.
Get the latest news delivered to your inbox.
Related articles