Crowd roars, squealing tires and Beatles audio: Case for computers that can listen
Sound often reveals what the eyes miss, and an MIT professor wants machines to be...
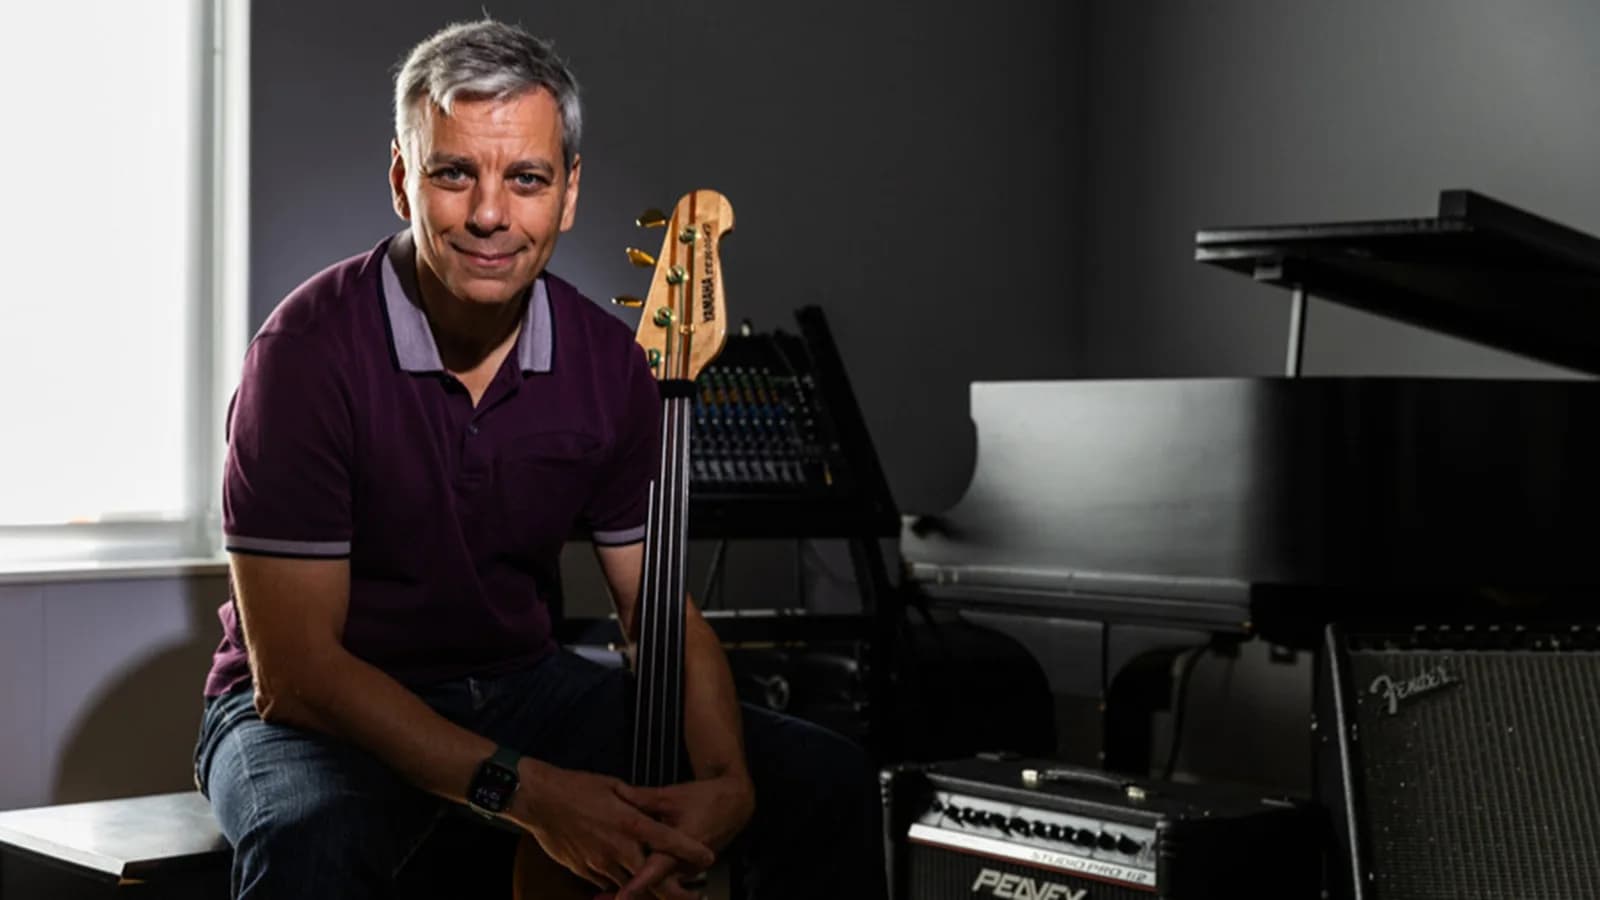
Sound often reveals what the eyes miss, and an MIT professor wants machines to be better listeners than people are. Paris Smaragdis, who joined MIT’s faculty in 2025, is working toward computers whose understanding of sound could one day exceed human hearing.
Such a system could locate a traffic accident by listening for squealing tires and crunching metal. It could also flag when an industrial drill boring through dense bedrock for a geothermal well is about to break.
Teaching machines to listen
His group works on machine learning for separating individual sounds from a mix, smart devices that augment people’s audio surroundings, and better tools for creating and analyzing music.
Smaragdis grew up in Greece, studied bass at Berklee College of Music and earned his MIT master’s degree and PhD at the Media Lab.
Early in his career, he chose a less common path. Many Media Lab students were using signal processing to help machines handle sound, but he turned to machine learning, which offered advantages that traditional techniques could not match.
His reasoning was that people do not fully understand how they hear themselves. “We can’t just tell them how to listen,” he said of computers, so they must learn it from data.
Crowd roars to Beatles
At Mitsubishi Electric Research Laboratories, he built AI systems that scan video soundtracks to work out what is happening on screen. A roaring crowd, for instance, can signal the highlights of a soccer match without any need to analyze the video.
That work later found its way into a personal video recorder, traffic monitoring systems and cell phones.
At the University of Illinois Urbana-Champaign, his group used neural networks to separate individual sounds from audio mixtures. The technique caught the attention of the team behind the 2021 documentary mini-series “The Beatles: Get Back,” which asked him to help clean up archival recordings.
The recordings posed different problems each time. In one clip, John Lennon plays music while Paul McCartney reads newspaper headlines and jokes about George Harrison. Smaragdis said the team looked for one technical solution that could handle everything rather than treating each problem separately. His contributions helped the team win a 2022 Emmy Award for sound editing for a nonfiction or reality program.
New directions at MIT
After 15 years at Illinois, Smaragdis moved to MIT to tackle interdisciplinary problems emerging in the field. His group now pursues two main goals.
The first is making computers more useful to musicians, including systems that learn how to listen to music so they can give constructive feedback. “We don’t want to use computers to replace musicians,” he said.
The second is building fundamental tools that scientists and artists can use to process, analyze and manipulate audio. His team is exploring algorithms for sophisticated signal processing in which traditional frames of reference, including sampling rates and context windows, are not fixed or even defined.
That points to computational structures that remain unexplored but could process audio more efficiently, he said. They are also exploring how to bring large language models into speech recognition and audio enhancement. Smaragdis said the ideal way to use AI for sound and music has not yet been found.
Smaragdis emphasizes hands-on lessons because few of his students have used computation with sound, so they can see and hear how equations become something tangible.
Related articles